Evaluation & Testing
Frameworks and platforms for scoring prompt and agent output: eval harnesses, LLM-as-judge tooling, benchmarks, red teaming and observability.
IntellAgent
A framework that builds a policy graph from an agent's prompt and generates simulated user conversations to diagnose where the agent breaks its instructions.
Promptmetheus
A prompt engineering IDE for composing prompts from reusable blocks, testing variants across providers and tracking cost and output quality for each version.
Coze Loop
ByteDance's open-source agent development platform covering prompt development and versioning, evaluation datasets and production observability in one loop.
FuzzyAI
A CyberArk fuzzing tool that applies a catalogue of jailbreak and obfuscation techniques against model endpoints to find prompts that bypass safety filters.
DataDreamer
A Python library for reproducible synthetic data and prompting workflows, with caching, resumable sessions and export of the full prompt history for a run.
Laminar
An open-source observability platform purpose-built for AI agents, combining span tracing, online and offline evaluations and labelling of production data.
Athina Evals
The open-source Python SDK behind the Athina platform, used to run evaluation suites over model responses and log the scored results for later comparison.
Future AGI
An open-source platform for tracing, evaluating and improving LLM and agent applications, with dataset management, prompt experiments and a hosted option.
Galtea
An evaluation platform aimed at regulated industries, providing structured test sets and reporting designed to support compliance evidence for AI systems.
Orq.ai
A European AI gateway and platform that routes requests to hundreds of models while providing prompt management, guardrails, spend caps and audit logging.
OpenCompass
An evaluation platform covering a large set of models and benchmark datasets, with distributed execution and configurable prompt templates for each task.
Braintrust
An evaluation and observability platform for AI products, with a prompt playground, dataset management, scorers and production tracing in one workspace.
Vals AI
A company that builds private, domain-specific benchmarks for legal, tax and finance work and publishes independent model comparisons in those fields.
Fiddler AI
An enterprise AI observability and governance platform that monitors model behaviour, explains predictions and applies guardrails to agent workloads.
LastMile AI
A developer platform for building and evaluating AI applications, known for the open AIConfig prompt format and small purpose-built evaluator models.
Scorable (Root Signals)
An evaluation platform, formerly Root Signals, focused on building and calibrating custom LLM-as-a-judge evaluators so scores match human judgement.
Deepchecks
The commercial platform from the Deepchecks team for continuous validation of LLM applications, with automated test suites and version comparison.
AgentEvals
A companion LangChain package focused on scoring agent trajectories, comparing the sequence of tool calls an agent made against an expected path.
Scorecard
An evaluation platform for AI products with test set management, scoring runs and a prompt playground, priced by the number of scores computed.
Evidently Cloud
The hosted service from the Evidently team for running AI evaluations and monitoring at team scale, built on their open-source metric library.
Awesome Evals
A curated library of resources for building and evaluating AI agents, collecting papers, talks, blog posts and evaluation tools in one list.
RagaAI Catalyst
A Python SDK for agent observability and evaluation, with tracing of agent, tool and model spans plus built-in metrics and guardrail checks.
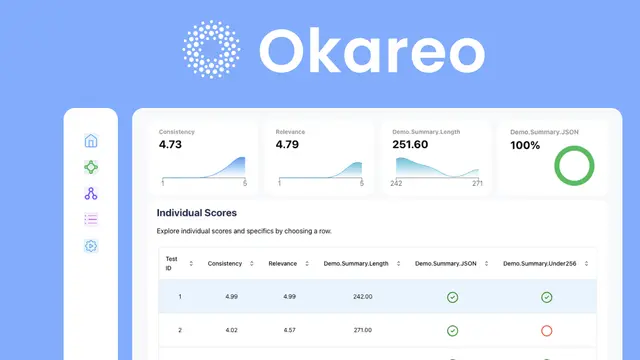
Okareo
A testing platform that generates synthetic users to exercise voice and text agents, surfacing edge cases before real customers hit them.
HoneyHive
An observability and evaluation platform for agents, combining tracing, datasets, prompt experiments and human review in one workspace.
Giskard
The commercial platform from the Giskard team for red teaming and securing LLM agents, built on their open-source scanning library.