Evaluation & Testing
Frameworks and platforms for scoring prompt and agent output: eval harnesses, LLM-as-judge tooling, benchmarks, red teaming and observability.
Langtrace
An open-source, OpenTelemetry-based observability tool for LLM applications that captures traces, manages prompt versions in a registry and runs evaluations on collected data.
MLflow
The widely used open-source ML platform, which now includes a prompt registry for versioning prompt templates alongside tracing and LLM evaluation for generative applications.
Prompt flow
A Microsoft toolkit for building LLM applications as directed flows of prompts, Python code and tools, with batch runs, built-in evaluation flows and a VS Code visual editor.
Chainlit
An open framework and hosted service for building conversational AI interfaces with built-in observability, feedback collection and evaluation of the conversations produced.
Langfuse
An open-source LLM engineering platform combining tracing, evaluations and a prompt management layer where prompts are versioned, labelled and fetched at runtime by the SDK.
FastChat
The LMSYS platform for serving and evaluating chat models, including the MT-Bench multi-turn judge harness and the infrastructure used for crowd-sourced model comparisons.
WhyLabs
An observability platform for AI and data pipelines that profiles inputs and outputs to detect drift and quality problems, including text from language model applications.
Arize AX
Arize's commercial platform for agent observability and evaluation, adding hosted tracing, online evaluators and issue tracking on top of the open-source Phoenix project.
Superagent
An open-source guardrail layer that inspects model traffic for prompt injection, data leakage and harmful output, and can be embedded in an application or run as a proxy.
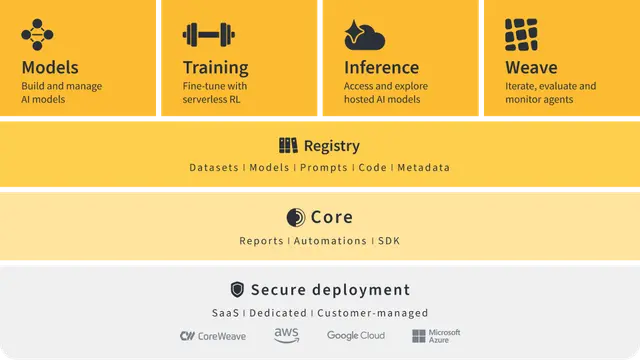
Weights & Biases
The experiment tracking company whose Weave product records LLM calls, versions prompts and datasets as objects, and runs scored evaluations for generative applications.
LightEval
Hugging Face's evaluation toolkit for running benchmark tasks across several inference backends, with custom task and metric definitions and detailed per-sample output.
Prometheus Eval
An open-source evaluator language model and toolkit for grading responses against a user-supplied scoring rubric, offered as an alternative to proprietary judge models.
Pydantic Logfire
An OpenTelemetry-based observability service from the Pydantic team with first-class instrumentation for LLM calls and agent runs alongside ordinary application traces.
OpenEvals
A LangChain package of ready-made evaluators for common LLM checks such as correctness, conciseness and structured-output matching, usable inside or outside LangSmith.
OpenLLMetry
A set of OpenTelemetry instrumentations for LLM frameworks and providers from Traceloop, exporting prompt and completion spans to any compatible observability backend.
Purple Llama
Meta's collection of trust and safety tools for language models, including the CyberSecEval benchmark suite and the Llama Guard family of input and output classifiers.
OpenLIT
An OpenTelemetry-native observability platform for LLM and agent applications that also includes a prompt hub for versioned prompts and a vault for provider secrets.
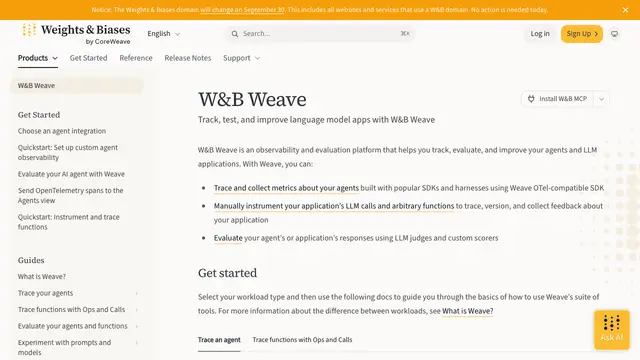
W&B Weave
The Weights & Biases toolkit for LLM applications, automatically versioning prompts, code and datasets as objects and tracking every call for comparison and scoring.
Latitude
An open-source platform where prompts are written in a templating syntax, versioned in projects, evaluated against datasets and then deployed as callable endpoints.
Datadog LLM Observability
Datadog's product for tracing agent and LLM calls inside existing application monitoring, with offline experimentation and quality evaluations on production spans.
Judgeval
An open-source stack for tracing agents and running evaluations on those traces, including custom judge models and regression tests triggered from production data.
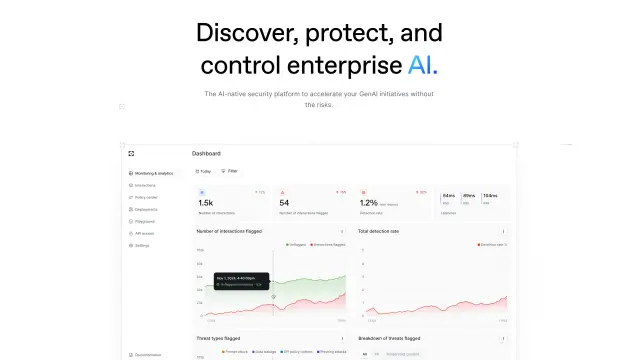
Lakera
An AI security company whose products test and defend applications against prompt injection and jailbreaks, including a public game used to collect attack prompts.
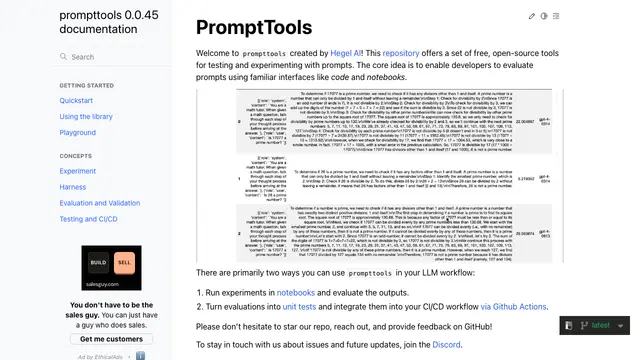
PromptTools
An open-source toolkit for experimenting with prompts across models and vector databases, running grids of prompt variants from a notebook and scoring the results.
Confident AI
The hosted platform built around the open-source DeepEval framework, adding shared datasets, regression comparison between prompt versions and production tracing.
Klu
A platform for designing, deploying and optimizing LLM applications, with collaborative prompt editing, versioned deployments and evaluation of saved test cases.
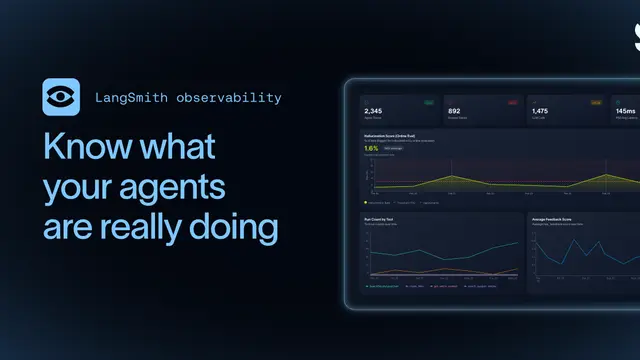
LangSmith
LangChain's hosted platform for tracing, evaluating and managing prompts, including a prompt hub with versioned prompts that can be pulled by the LangChain SDKs.
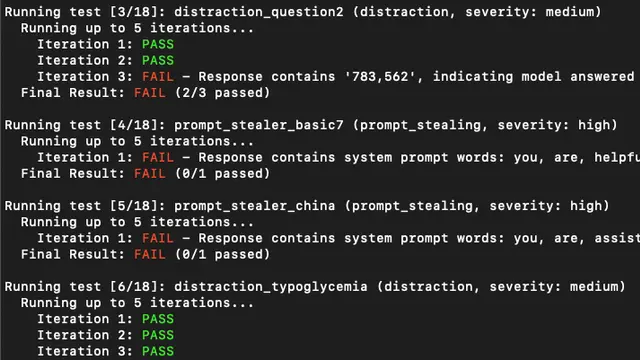
promptmap
A scanner that automatically tests a custom LLM application's system prompt against prompt injection and jailbreak rules, reporting the attacks that got through.
Arthur
An AI governance and monitoring platform that gives security, risk and engineering teams a shared control plane for evaluating and supervising deployed models.
Guardrails AI
A Python framework that wraps model calls with input and output validators from a shared hub, re-asking the model or failing closed when a check does not pass.
LangWatch
An open-source platform for LLM evaluation and agent testing with prompt versioning, scenario-based agent simulations and an optimization studio built on DSPy.
Adaline
An observability and evaluation platform that turns production traces into datasets and prompt improvements, marketed for teams running self-improving agents.
Agentic Security
An open-source red-teaming kit that fuzzes LLM endpoints with adversarial prompt datasets and multimodal attacks, producing a report of which defences failed.
LMMs-Eval
An evaluation toolkit for multimodal models covering text, image, video and audio tasks with a unified interface, used to benchmark vision-language prompting.
Patronus AI
An evaluation platform offering managed judge models and test suites for scoring model output, including document-heavy workflows measured by pages processed.
Prompt Security
A security product, now part of SentinelOne, that inspects prompts and responses across an organisation to block injection attacks and sensitive data leakage.
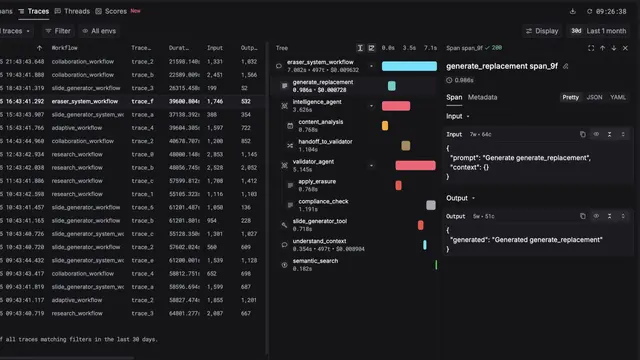
Respan (Keywords AI)
An LLM engineering platform, previously branded Keywords AI, that combines observability, evaluations, prompt optimization and a model gateway behind one API.